

/cnpg): the fleet, backups and recovery evidence, declarations, pooling and the operator. Each Cluster has a page organized by task (what needs attention, replication, storage, performance, backups) and guarded actions such as switchover, fencing, backup setup and restore, each followed until Radar observes the outcome. Radar does not provision object storage or credentials. Design detail is in cnpg.md.
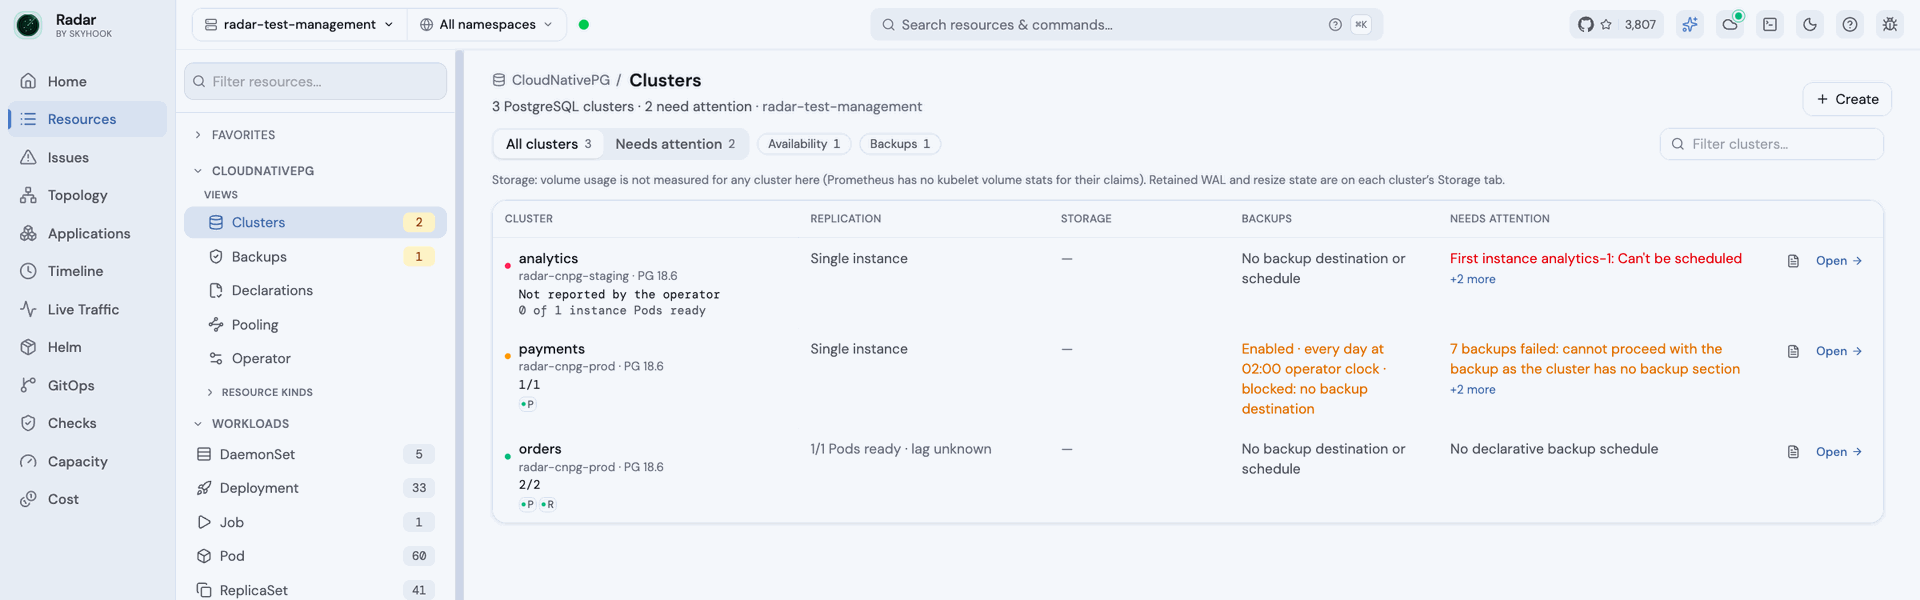
Fleet: every Cluster ordered by urgency, each with its top problem.
What Radar Shows
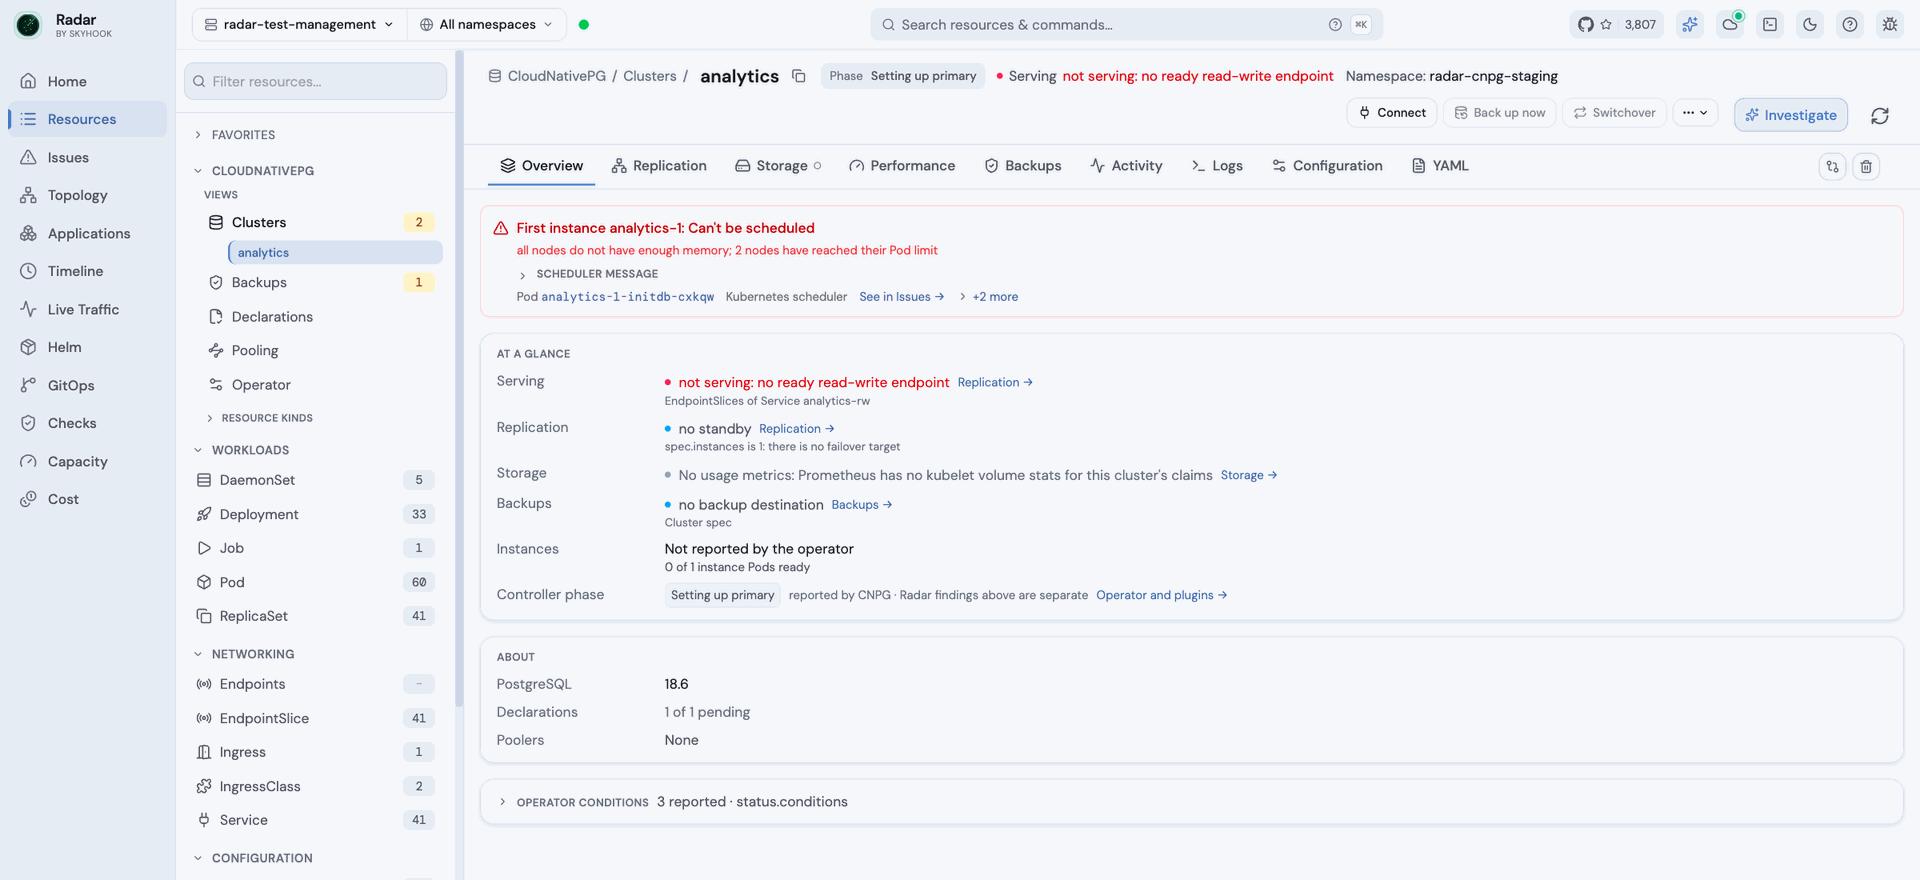
Cluster Detail View:- Phase, instances ready/desired, primary instance, image version
- Instance node distribution (which K8s nodes run each PostgreSQL instance)
- Storage configuration: data size, storage class, WAL storage
- Backup configuration: destination, retention policy, last successful backup, recovery point
- Monitoring: PodMonitor integration, custom query ConfigMaps
- Replication settings (for replica clusters), with per-instance role and timeline ID
- PostgreSQL parameters
- Health detection (AlertBanner for degraded clusters, failover/switchover in progress)
- WAL archiving failure - a first-class AlertBanner driven by the
ContinuousArchivingcondition. This is the classic silent CNPG incident: the cluster keeps serving traffic normally while the recovery point stops advancing. The condition proves the last archive attempt failed, so Radar reports “archiving failing since <time> - the recovery point may not be advancing” and deliberately does not claim an exact RPO - Last-backup failure - driven by the
LastBackupSucceededcondition. CNPG also sets this condition False with reasonBackupStartedwhile a backup is merely in flight; Radar ignores that state rather than alerting on every backup run
- Phase, backup method, duration, start/stop timestamps
- Cluster reference with clickable link
- Destination path and server name
- Backup target
- Failure detection (AlertBanner with error message)
- Cron schedule, last/next schedule timestamps
- Suspension detection (AlertBanner when paused)
- Backup configuration: cluster reference, method, owner reference settings
- Type (read-write/read-only) with colored badge, pool mode
- Instances scheduled/desired (not readiness - see below)
- Cluster reference with clickable link
- PgBouncer parameters
- Degraded state detection (AlertBanner when not all instances are scheduled)
Pooler.status.instances counts pods trying to be scheduled, not ready pods - a Pooler whose PgBouncer pods are all Pending still reports the full count. Radar labels the declared spec.instances count neutrally as N instances requested; actual readiness lives on the Deployment CNPG generates for the Pooler (same name, same namespace).
Resource Browser: Smart columns show status, instance counts (with degraded highlighting), primary instance, image tag, storage size, cluster reference, and schedule expressions.
Phase classification
Cluster phases are full English sentences (Cluster is unrecoverable and needs manual intervention), not enum tokens, and are matched on equality. They are bucketed as healthy / transient / failing / terminal / attention; terminal phases outrank instance counts, so an unrecoverable cluster whose pods happen to still be Ready is still rendered red. “Terminal” means reconciliation is blocked, not that the operator gave up: it retries every one of them, the plugin phases clear on their own once the plugin loads and answers, and the banner quotes the operator’s status.phaseReason. An unrecognized phase from a newer CNPG minor surfaces verbatim as unknown rather than being guessed at.
Backup phases are lowercase tokens. walArchivingFailing is treated as a cluster-level signal, not an ordinary backup failure - archiving is broken upstream of that Backup, so the whole recovery window is affected.
The taxonomy is defined twice - TypeScript for the badge, Go for the issue detector - and pinned by TestCNPGPhaseTaxonomyMatchesFrontend, which fails if the two drift.
Backup: in-tree vs the barman-cloud plugin
In-treespec.backup.barmanObjectStore is deprecated as of CNPG 1.26. Clusters migrated to the barman-cloud plugin keep their config in an ObjectStore CR (barmancloud.cnpg.io/v1), and CNPG stops populating status.lastSuccessfulBackup / firstRecoverabilityPoint by design. Radar detects the plugin from spec.plugins[], names the ObjectStore and resolved server key, and says so explicitly - rather than rendering an empty backup section that reads identically to “no backups configured”.
The ObjectStore itself is rendered: destination and credential provider (never the credentials), retention, and status.serverRecoveryWindow per PostgreSQL server - firstRecoverabilityPoint, lastSuccessfulBackupTime, lastFailedBackupTime. Note the field names differ from the Cluster’s (lastSuccessfulBackupTime, not lastSuccessfulBackup); reading the Cluster’s spelling off an ObjectStore silently yields nothing.
Two states carry the weight. A failure newer than the last success means the window has stopped advancing while its oldest point still ages out under retention - shrinking from both ends, so it is called out rather than left to be inferred from two timestamps. An ObjectStore with an empty serverRecoveryWindow is reported as holding nothing restorable rather than as healthy: on the plugin path the Cluster publishes no recovery point of its own, so a green badge here would be the only claim on screen and it would be wrong.
Backup and ScheduledBackup with spec.method: plugin name the plugin and suppress the in-tree destinationPath / serverName rows, which are never populated on that path. For barman-cloud, their destination comes from the Cluster’s plugin entry; their own plugin parameters are ignored. The standalone renderers explain this without presenting a parameter as a destination link. Workspace destination links are inferred from the current Cluster configuration. Radar does not model third-party plugin destinations.
Declarative objects: Database, Publication, Subscription
CNPG can manage PostgreSQL-side objects from Kubernetes. All three report throughstatus.applied, and it has three values, not two: true, false with the operator’s message, and absent - meaning not reconciled yet. Absent is rendered as pending rather than failed; treating it as failure condemns every object in its first seconds.
The names in these specs are PostgreSQL names, not Kubernetes names: a Publication demo-app-pub declares dbname: demo_app, and the Database CR that owns demo_app is called demo-app. Radar resolves them back to the CRs so the reference is a link rather than a dead string, and falls back to plain text when nothing matches. The Database detail runs the lookup in the other direction, listing what publishes from and subscribes into it - a link the API only models one way.
databaseReclaimPolicy (and its publication/subscription twins) decides whether deleting the manifest drops the real object. delete is called out as destructive; CNPG defaults to retain, and defaulting the other way in the UI would warn about data loss that is not going to happen.
A declared object the operator could not apply raises an Issue (CNPGDeclarativeNotApplied, warning) carrying the operator’s own message. This is the one CNPG failure with no other signal: the CR exists, the cluster is healthy, every count is green, and the database simply is not there. Only applied: false raises it - an absent applied means not yet reconciled, and reporting that would flag every declarative object for the first seconds of its life.
Image catalogs
ImageCatalog and ClusterImageCatalog pin one PostgreSQL image per major version. A Cluster that references one carries no spec.imageName at all; the resolved image lives in status.image, so anything reading spec alone shows a dash where an image is running.
A cluster asking for a major the catalog does not list reports “incomplete or invalid image catalog” and stops - and that is invisible from the cluster side, where the reference looks fine. The catalog page lists the clusters pinned to it and separates out those asking for a version it does not carry.
Cluster Audit checks
Deliberately narrow: the absence of a ScheduledBackup does not prove a cluster is unprotected (on-demand Backups, volume snapshots and external schedulers all exist), so the finding asserts only that no schedule is declared, at posture severity. All three
spec.method values - barmanObjectStore, volumeSnapshot and plugin - count as a declared schedule. Suspended schedules count as present, since suspension is deliberate operator intent. The check does not run at all unless a synced cluster-wide ScheduledBackup informer backs the inventory, because absence would otherwise be unprovable.
Supported CRDs
Limitations:
- The image-catalog and backup views describe what the cluster reports. A
ScheduledBackup’s cron is CloudNativePG’s six-field form (seconds first) and is shown verbatim rather than translated, because reading it as a five-field expression would state the wrong time.